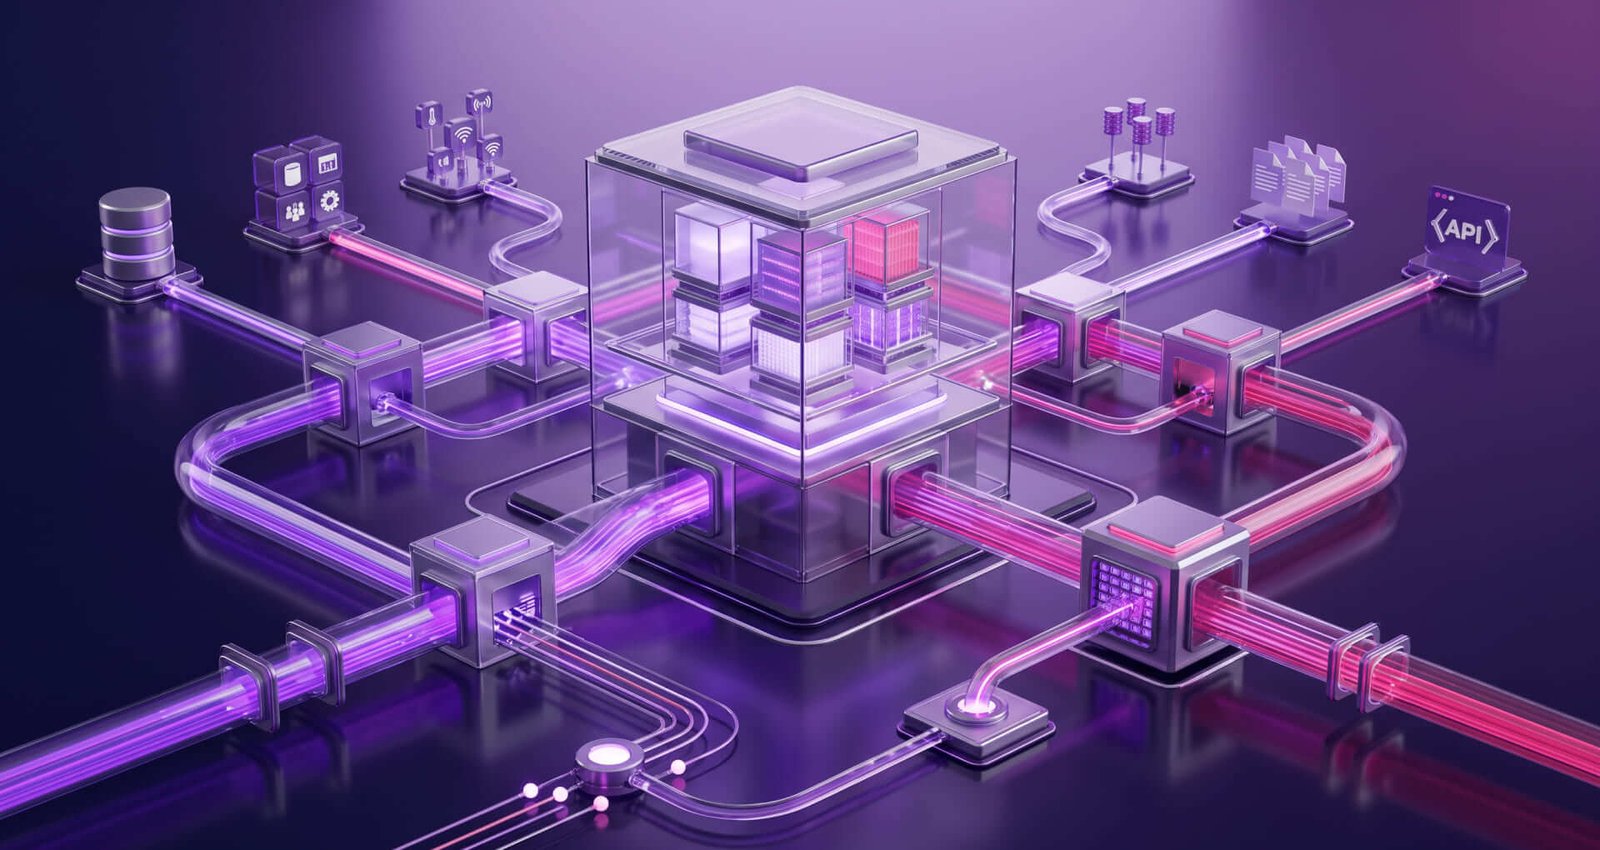

Data pipelines enable automated workflows by reliably transporting and transforming data from sources to destinations with codified steps. They create repeatable, auditable processes that preserve lineage and provenance for compliance and debugging. Core patterns ensure determinism and idempotent stages, while scheduling and orchestration manage dependencies, retries, and fault tolerance. Quality checks and modular components support scalable architectures. This framework yields actionable metrics and trust, yet practical choices and tradeoffs still determine how smoothly it scales in real-world workloads.
What Data Pipelines Do for Automated Workflows
Data pipelines are the backbone of automated workflows, ensuring data moves reliably from source to destination with minimal human intervention. They enable repeatable, auditable processes by codifying steps, checks, and schedules.
Data lineage clarifies origins and transformations, while data provenance preserves context and trust, supporting compliance and debugging. The result is scalable automation with transparent, reproducible data ecosystems.
Core Patterns That Drive Reliable Pipelines
Core patterns underpinning reliable pipelines center on determinism, observability, and modularity. They enable reproducible results through explicit contracts, versioned data, and idempotent steps. Data lineage clarifies origin and transformations, while schema evolution accommodates change without disruption. Observability and metrics drive accountable maintenance, alerting, and rapid recovery. Modularity supports composable pipelines, enabling scalable, freedom-respecting workflows that endure under evolving workloads.
Building Blocks: Quality, Scheduling, and Orchestration
Quality, scheduling, and orchestration form the essential building blocks of dependable data pipelines: Quality checks ensure correctness at every stage; Scheduling coordinates timely execution; Orchestration manages dependencies, retries, and fault tolerance.
The block trio supports latency accounting, schema evolution, and data validation, while retry policies enforce resilience.
Efficient, scalable, reproducible workflows empower freedom-seeking teams to adapt pipelines with confidence.
Practical Tips to Boost Timeliness and Trust in Data Flows
What practical steps can teams take to improve both timeliness and trust in data flows without sacrificing reliability? Establish clear data lineage, documenting sources, transformations, and ownership.
Automate monitoring for data freshness, with alert thresholds and self-healing retries.
Embrace immutable pipelines and versioned schemas to enable reproducibility.
Use lightweight governance, promote transparency, and measure success with actionable, real-time cadence metrics.
See also: propagatenetworks
Frequently Asked Questions
How Do Pipelines Handle Data Schema Evolution Over Time?
Data pipelines handle data schema evolution through data versioning and monitoring for schema drift, enabling compatibility layers, automated migrations, and rollback capabilities while preserving reproducibility, scalability, and freedom to adapt workflows without disrupting downstream consumers.
What Are the Trade-Offs Between Batch and Streaming Pipelines?
A lightning bolt splits the workflow—batch latency versus streaming scalability, illustrating trade-offs. Batch emphasizes predictability and cost control, while streaming prioritizes immediacy and elasticity; each balances reliability, throughput, and fault tolerance for varying operational freedom.
How Is Data Lineage Tracked Across Complex Workflows?
Data lineage is tracked through metadata catalogs, audit trails, and event logs, ensuring traceability across orchestration steps. It reveals workflow dependencies, enabling scalable governance, reproducible experiments, and freedom to optimize pipelines without compromising accountability.
What Governance Controls Ensure Compliant Automated Data Flows?
“Forewarned is forearmed.” Governance controls ensure compliant automated data flows through auditable policies, role-based access, lineage tracking, and continuous monitoring, emphasizing governance compliance and data quality; a scalable, reproducible framework favors freedom while enforcing traceable, consistent processes.
How Do Pipelines Recover From Partial System Failures?
Pipelines recover from partial system failures via robust retry strategies and fault isolation, enabling automatic reruns, isolated error handling, and stateful checkpoints. This approach supports efficient, scalable, reproducible workflows that preserve freedom to deploy changes confidently.
Conclusion
Data pipelines synchronize complexity into predictable outcomes, turning scattered data into reliable insights. They act like a well-tuned railway system: each car (step) follows a scheduled track, stays on time, and logs every connection. In one team’s project, a failed nightly run prompted an audit that revealed a single misspinned dependency; fixing it unlocked a week’s worth of dashboards. The result: scalable, reproducible flows that boost timeliness, trust, and auditable provenance at every stop.